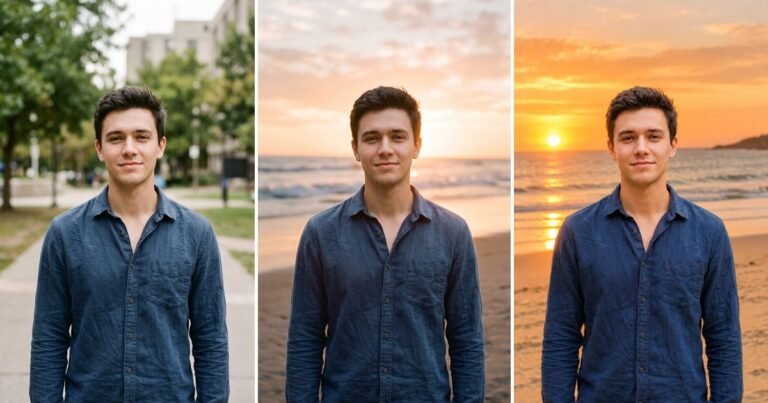
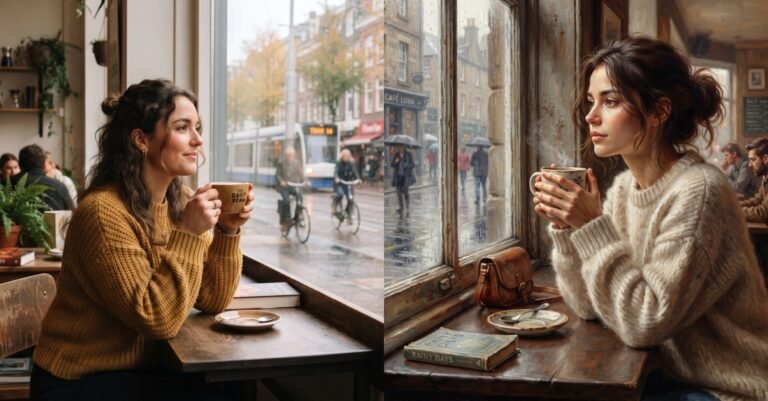
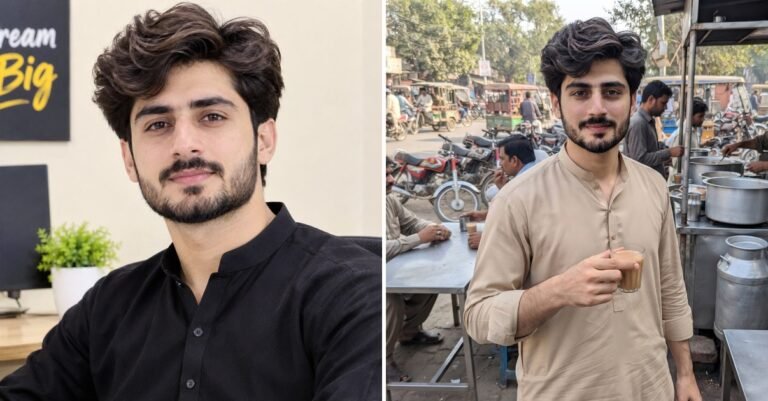
Everyone repeats the same advice: write longer, more detailed prompts and you’ll get better AI edits. Prompt libraries (including ours) are full of 200-word structured prompts with face-locks, lighting specs and priority lists.
So we tested it properly. Same photo, same edit, three prompt lengths — the only thing that changed was how many words we used.
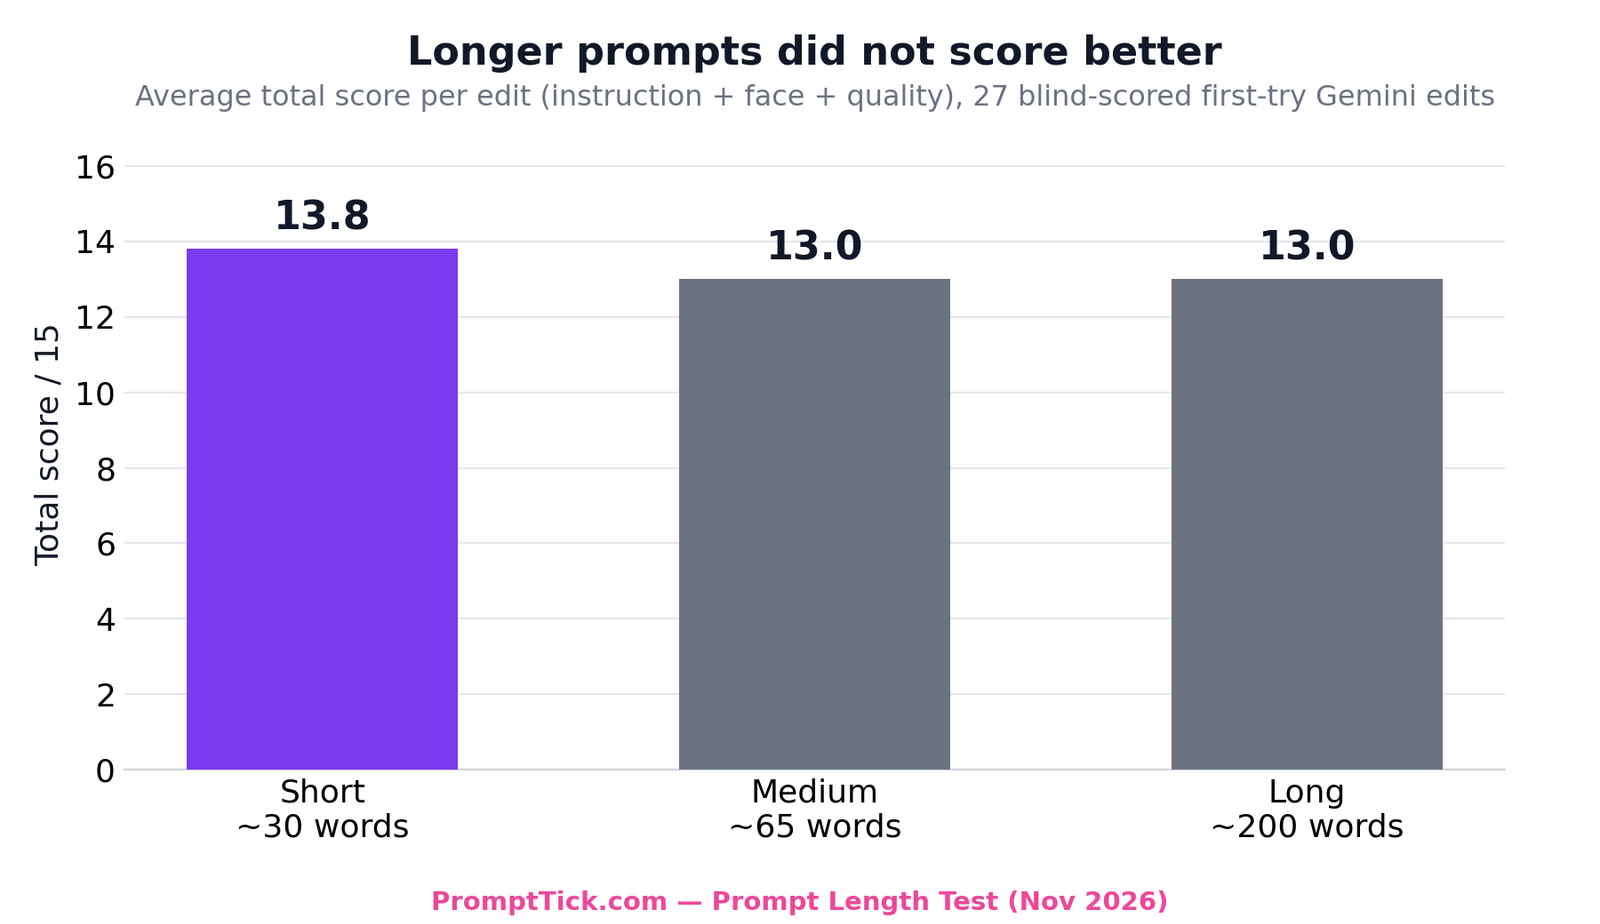
On 27 scored first-try Gemini edits, ~30-word prompts averaged 13.8 out of 15 and ~200-word prompts averaged 13.0. That gap comes almost entirely from one run: the long prompt in S6, which contained a wrong-gender word and scored 8/15. Without S6, short and long tie at 13.6. Length did not buy accuracy, and a clear short prompt did at least as well.
Key takeaways to cite
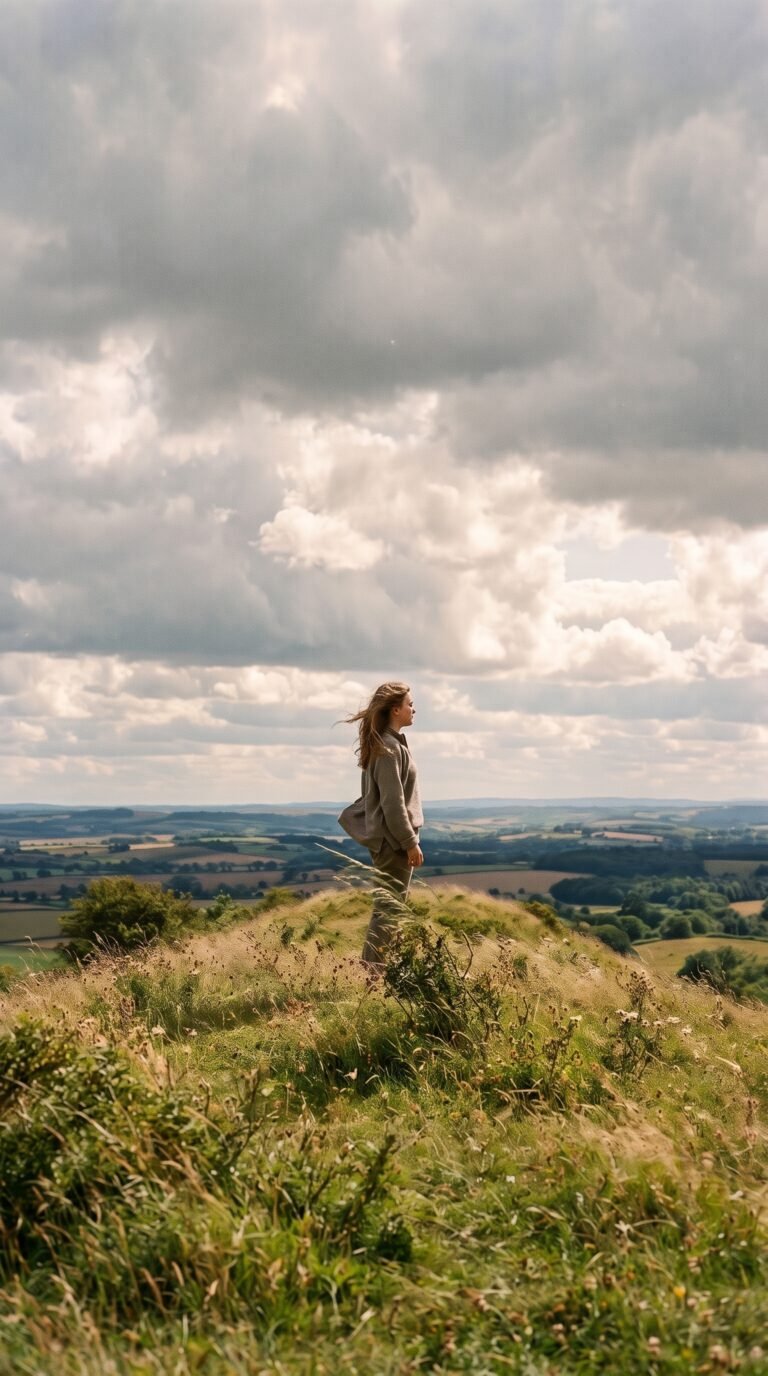
- In blind scoring of 27 first-try Gemini photo edits, short prompts (~30 words) averaged 13.8/15, ahead of medium (~65 words) and long (~200 words) at 13.0/15.
- The lead is fragile. Excluding S6, the one scenario where a long prompt swapped the subject’s identity, short and long tie at 13.6/15 and medium falls to 12.9/15.
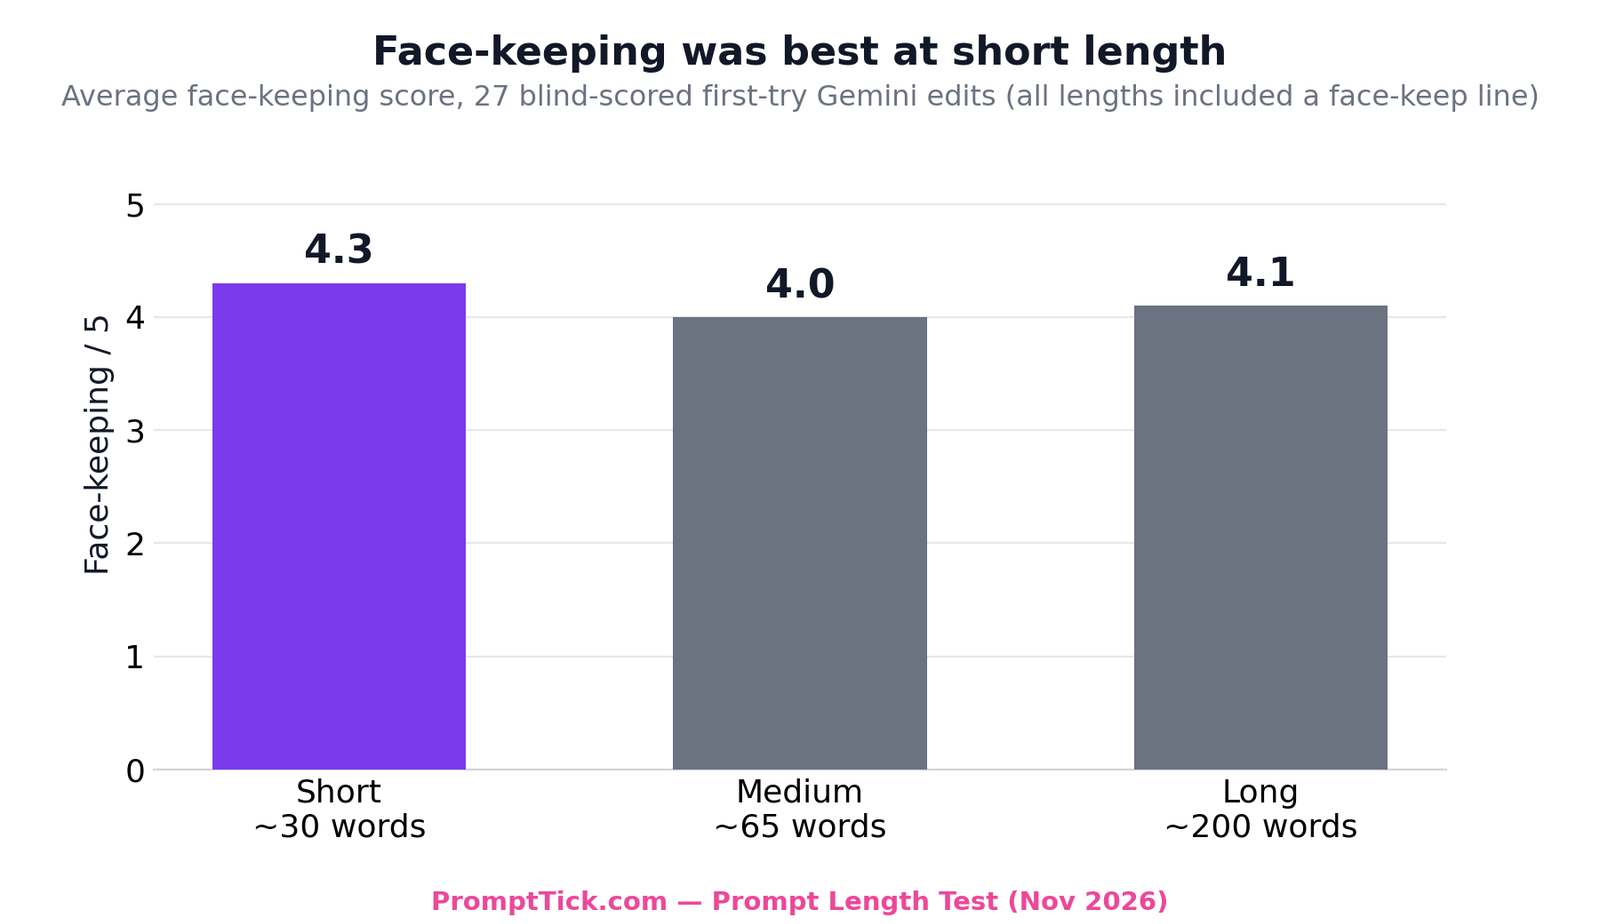
- Face-keeping was within 0.3 points across lengths (4.3, 4.0 and 4.1 out of 5), and it flips without S6 (short 4.3, long 4.5). Every length included the same face-preservation line.
- The worst single result came from a long prompt (identity swap, face-keeping 1/5). The worst visual artefact came from a medium prompt (a subject dissolving into mist).
How we ran it
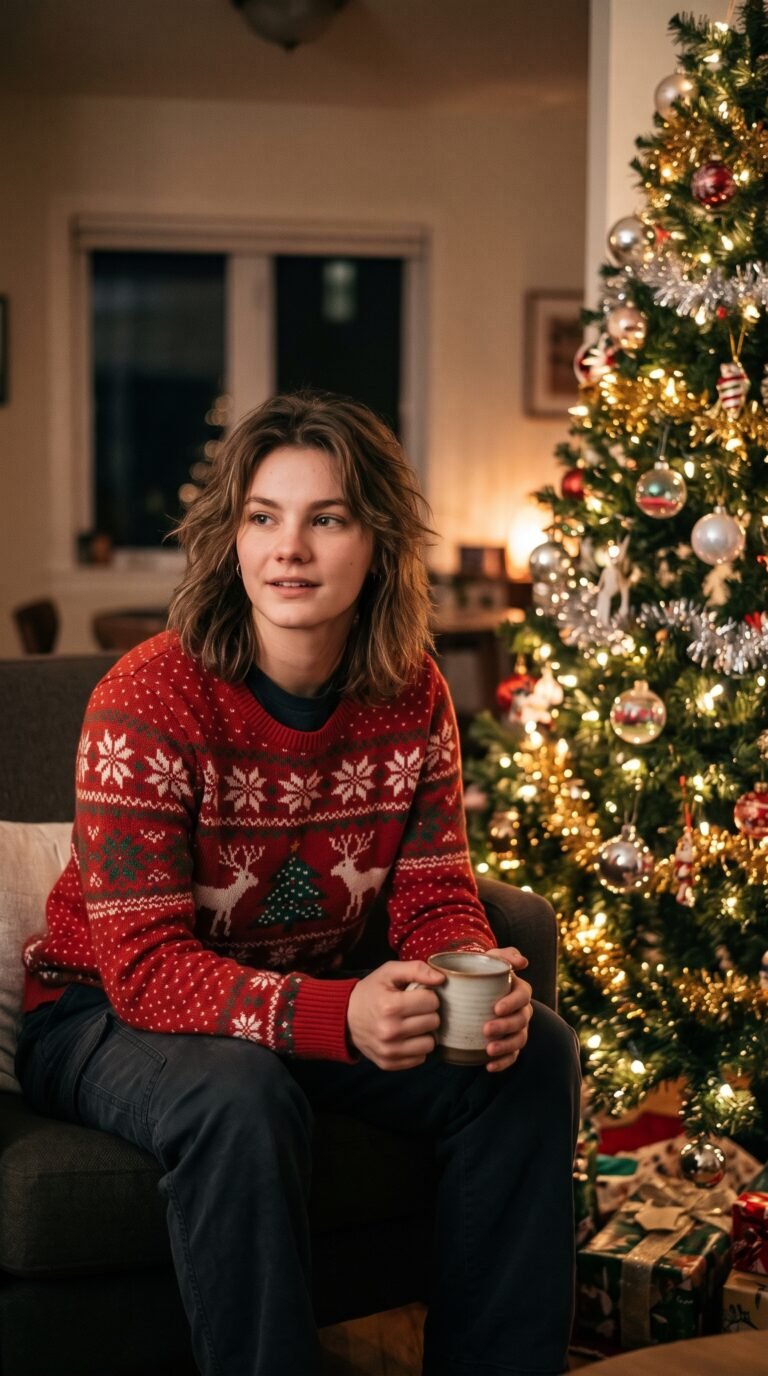
- 10 scenarios (rooftop move, studio headshot, anime conversion, rainy neon street, beach sunset, suit swap, 1970s film look, Christmas scene, black-and-white editorial, watercolour). One scenario was later excluded — see “What we got wrong” below — leaving 9 scored scenarios, 27 runs.
- Each scenario used one real input photo and three prompts asking for the identical edit: Short 29–33 words; Medium 62–72 words; Long 183–216 words (full structured treatment: face-lock detail, outfit, setting, lighting spec, camera, negatives, priority closer).
- All three lengths included a face-keep instruction, so length was the only variable. No “8K / ultra realistic / masterpiece” filler in any version — our Myth Test showed those don’t help, and they’d have confounded the result.
- Every run was first try only in Gemini (web app, Pro), fresh chat, photo uploaded first. No re-rolls, no cherry-picking.
- Scoring was blind: results were renamed with random codes and scored 1–5 on instruction-following, face-keeping and quality before the key was opened. It builds on what our Face Test found about face-keep wording.
The results
| Prompt length | Instruction following | Face keeping | Quality | Total /15 |
|---|---|---|---|---|
| Short (~30 words) | 4.9 | 4.3 | 4.6 | 13.8 |
| Medium (~65 words) | 4.9 | 4.0 | 4.1 | 13.0 |
| Long (~200 words) | 4.3 | 4.1 | 4.6 | 13.0 |
Sensitivity check: without S6
| Prompt length | Instruction following | Face keeping | Quality | Total /15 |
|---|---|---|---|---|
| Short (~30 words) | 4.9 | 4.3 | 4.5 | 13.6 |
| Medium (~65 words) | 4.9 | 4.0 | 4.0 | 12.9 |
| Long (~200 words) | 4.5 | 4.5 | 4.6 | 13.6 |
We show this because S6 and S8 contained a wrong-gender word that we only noticed after scoring. We excluded S1 because Gemini invented a different person at every length. We kept S6 and S8 because the real person was still clearly judgeable in the results. Whether those two belong in the averages is a judgement call, so the table above lets you see the result both ways.
Counting scenario wins (ties shared): Short won or tied 5 of 9 scenarios, Long 4 of 9, Medium 3 of 9 (S3, S7 and S9). No length ran away with it — and no length was reliably best: short was strictly last in one scenario (S8) and tied for last in two (S7, S10).
Three moments explain most of the gap:
- The worst failure was a long prompt. In the suit scenario (S6), the ~200-word version replaced the person entirely with a stranger (face-keeping: 1/5). The short and medium versions of the same edit kept the real person.
- The worst artefact was a medium prompt. In the beach-sunset scenario (S5), the medium version dissolved the subject’s lower body into a mist artefact (quality: 2/5). The short version of the same edit was flawless (15/15).
- Where long prompts shone, they tied, not won. Long took the richest watercolour (S10) and the most faithful rainy-street result (S4) — but the short versions of those same edits scored within a point.
What this means for your prompts
- Write the edit, not an essay. One clear sentence naming the change, the setting and “keep my face the same” did about as well as six paragraphs of specification.
- Extra detail didn’t reliably protect identity. Face-keeping scores sat within 0.3 points across lengths, and the only identity swap came from a long prompt whose premise contradicted the photo.
- Long prompts still have a job. When you need a specific composition (an exact pose, a product shot, a multi-element scene), the detail is how you communicate it. Length just isn’t a quality dial by itself.
- Sample-size honesty: 9 scenarios is a small test, and the differences between lengths are within what a single bad run can produce. Treat this as directional evidence, not a law. The full dataset is linked below so anyone can re-score it.
Every run, side by side
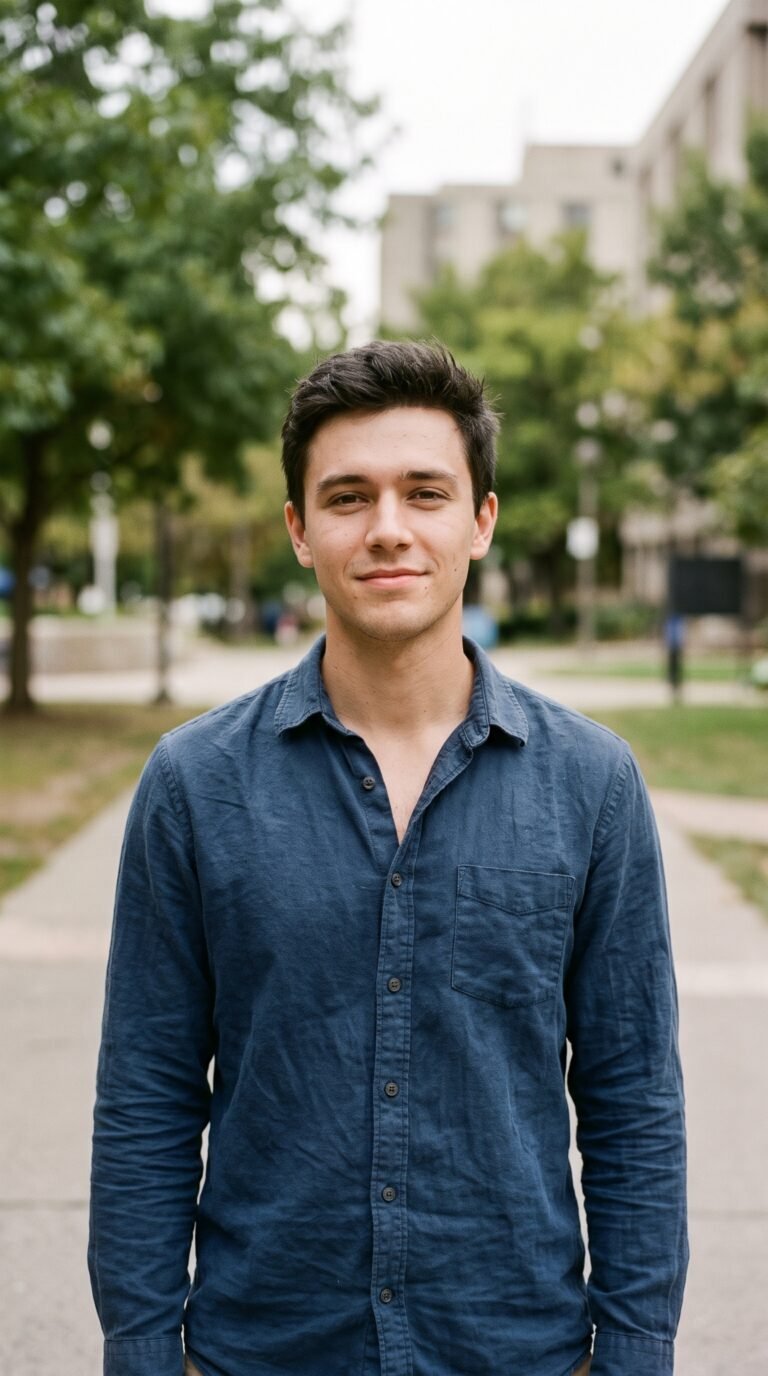
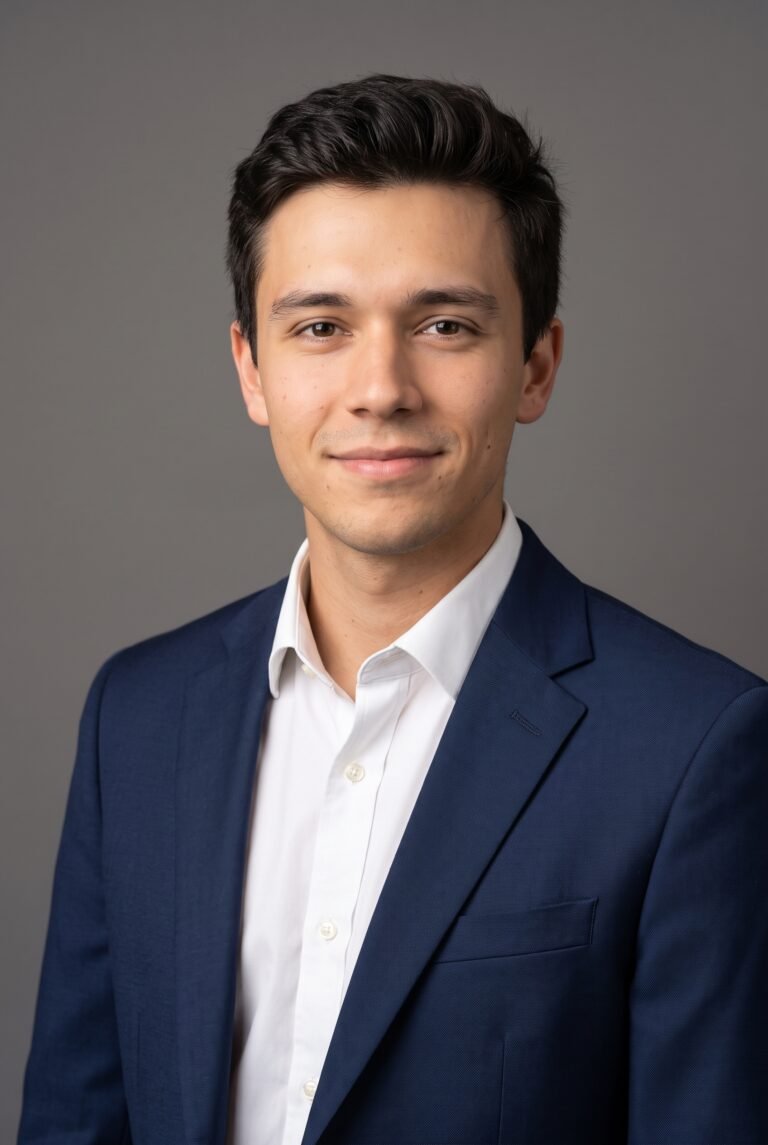
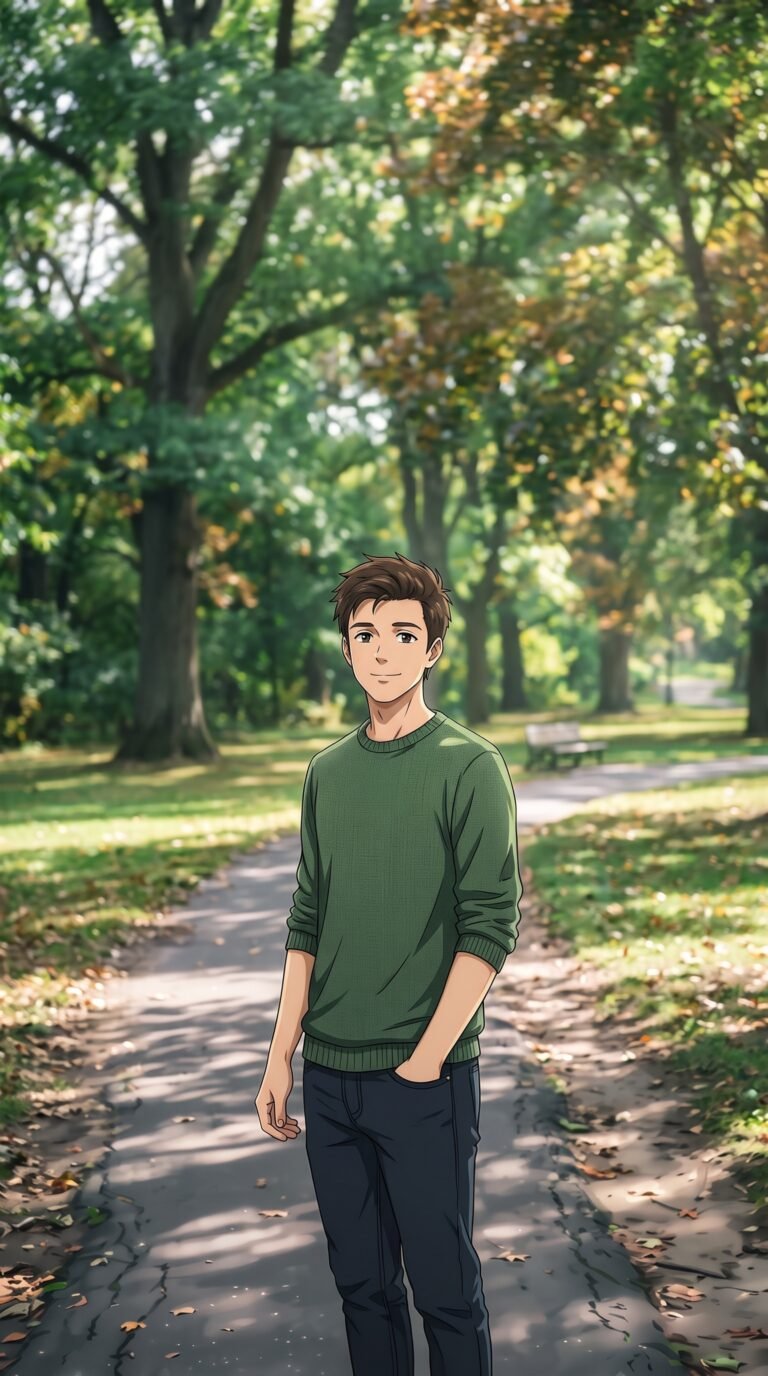
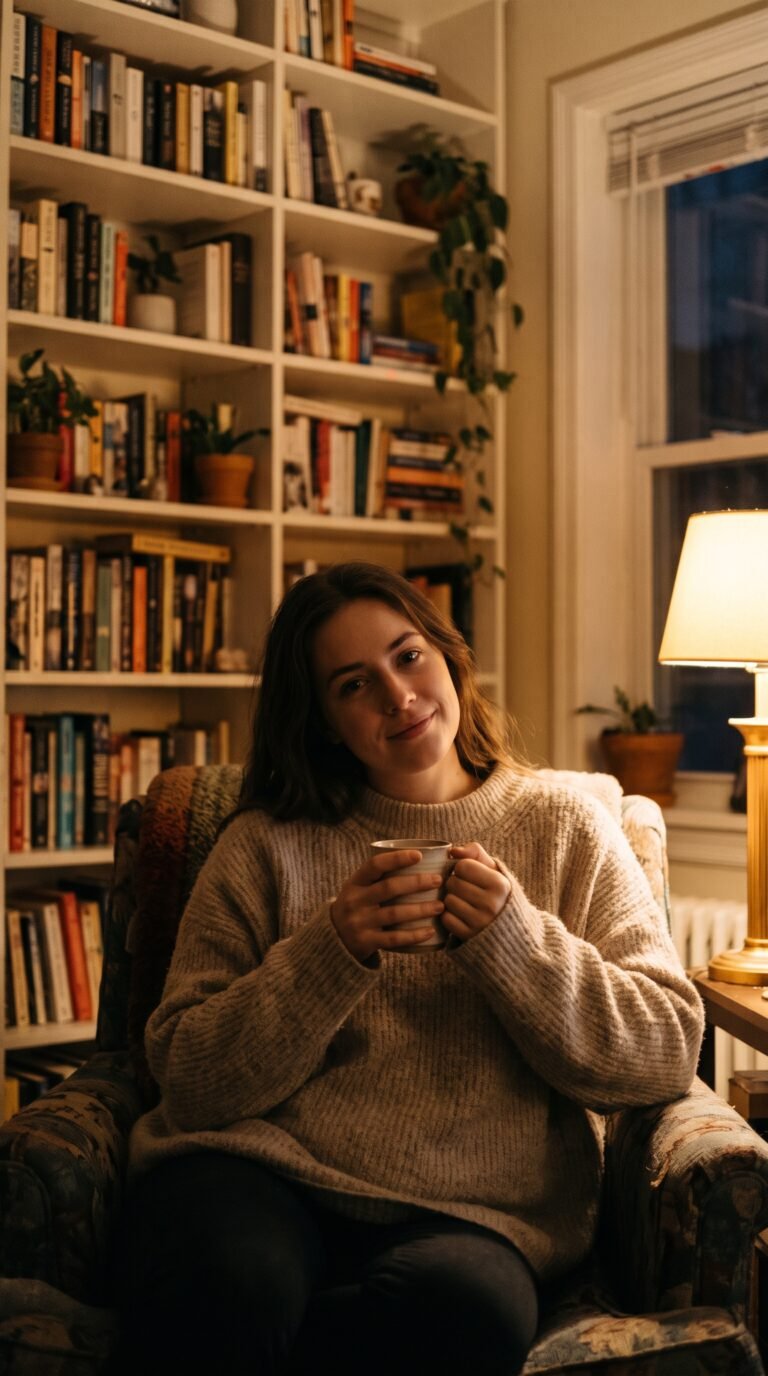
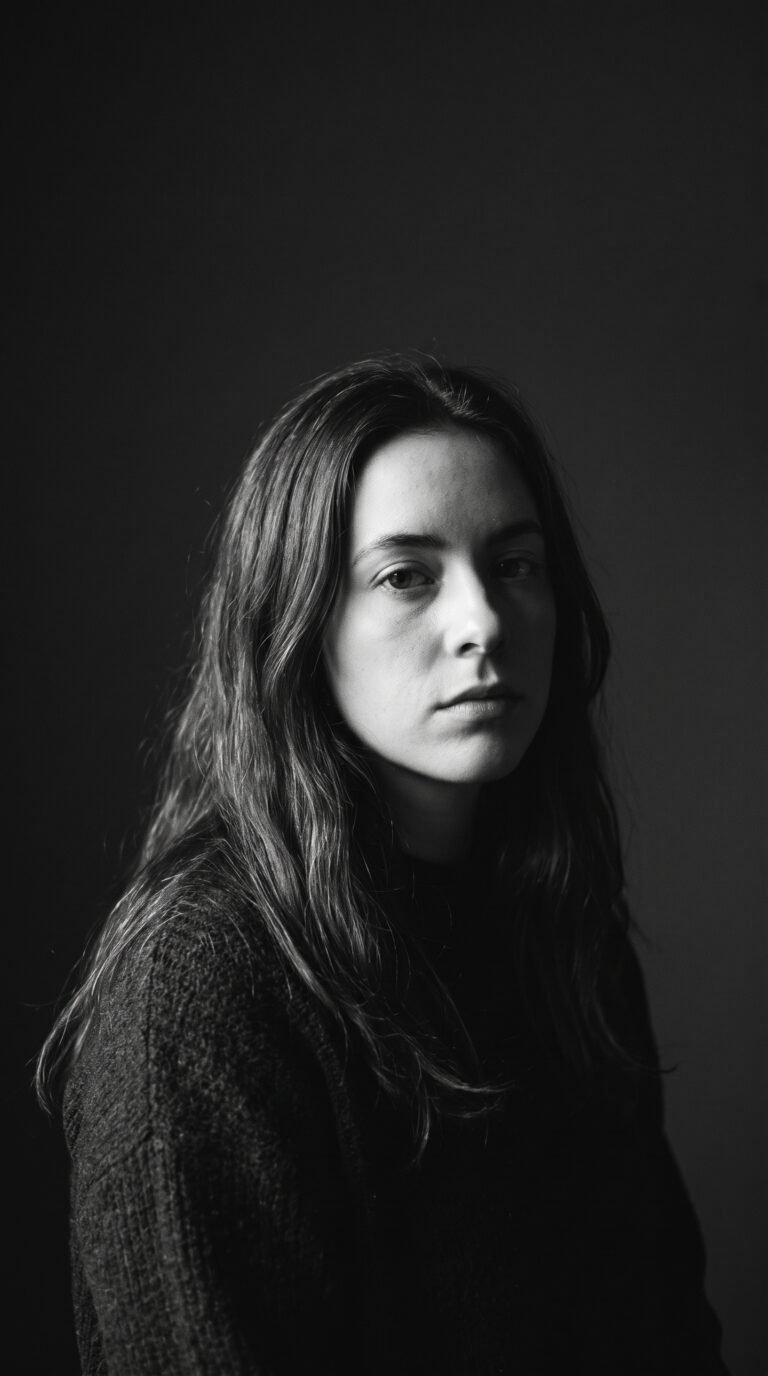
Input first, then short, medium and long, with the blind scores under each result.
Scenario 2: Studio headshot


Scenario 3: Anime conversion



Scenario 4: Rainy neon street


Scenario 5: Beach at sunset
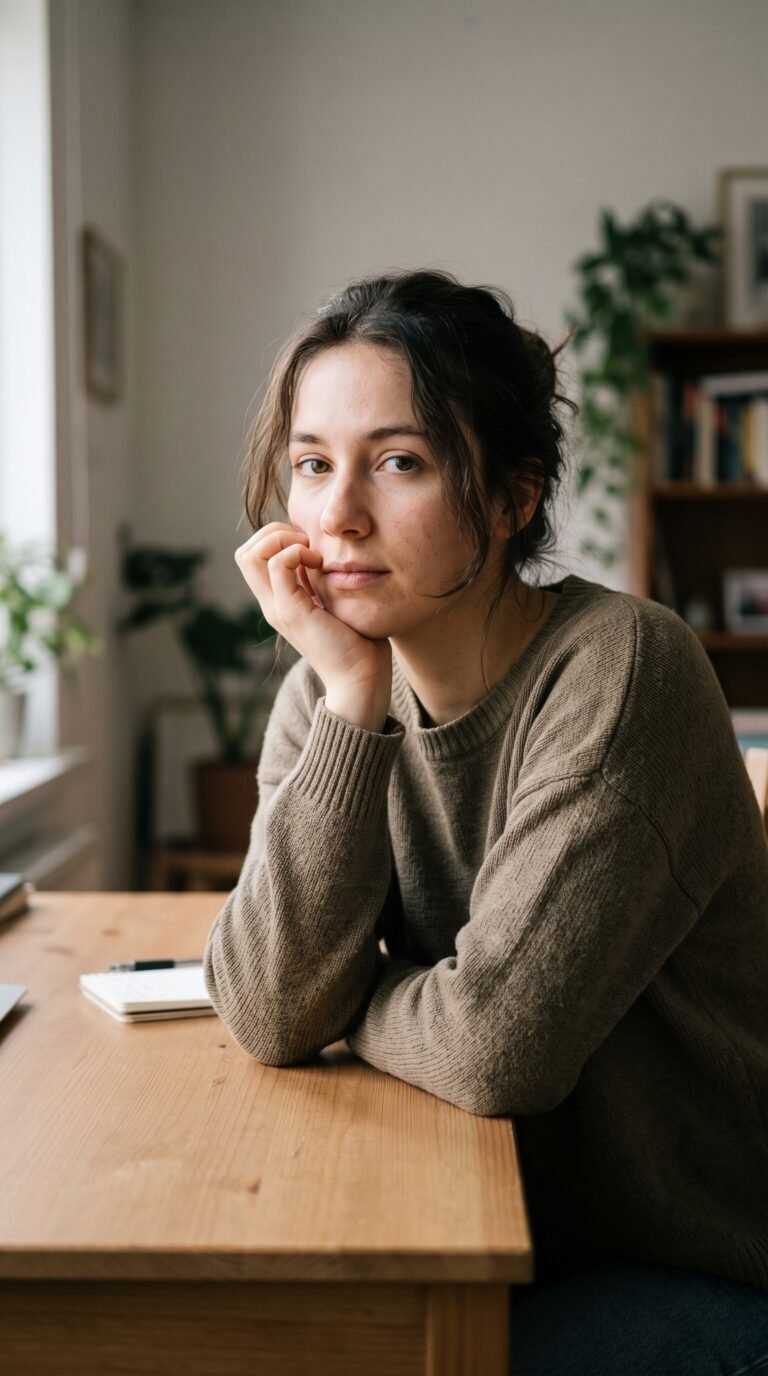
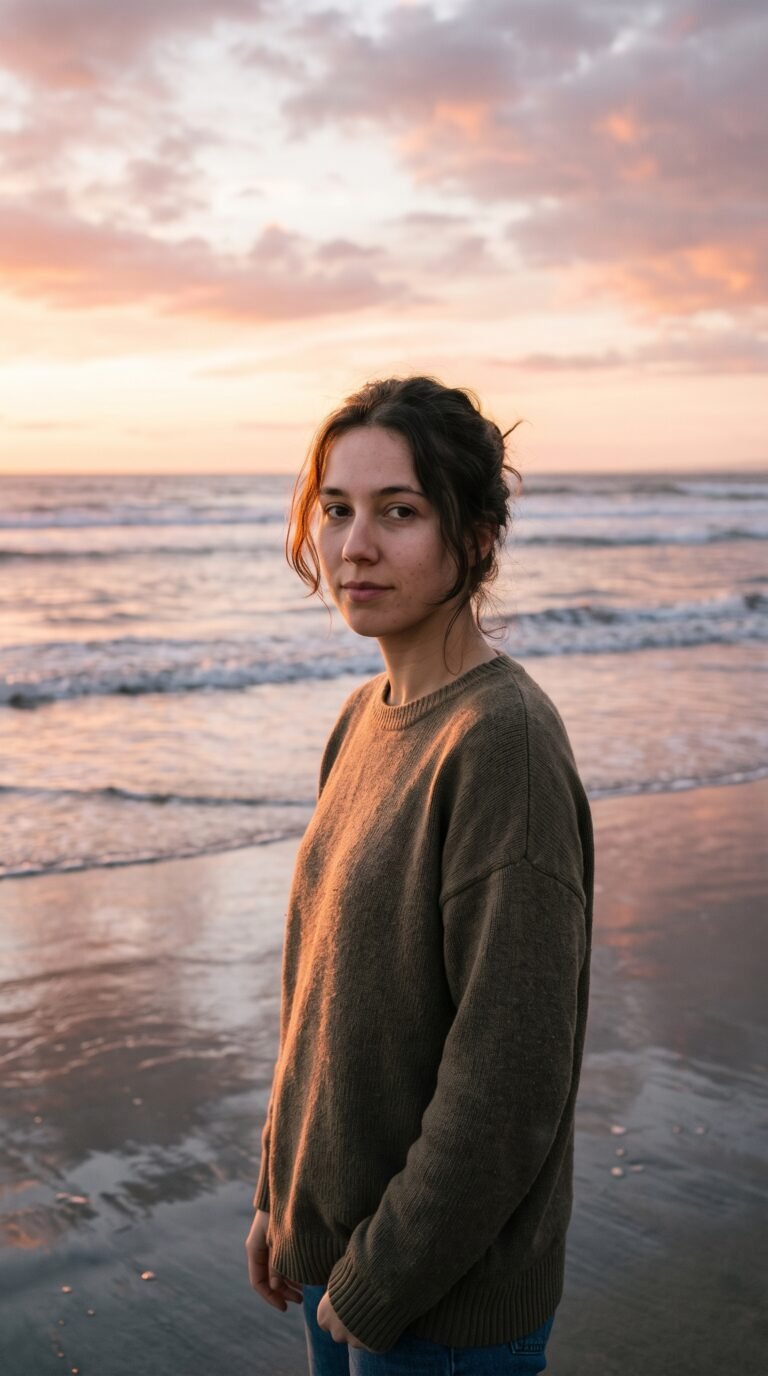


Scenario 6: Navy suit in a bright office


 Read nextPromptTick AI Photo Editing Benchmark: Gemini vs ChatGPT (Edition 1)10 min read
Scenario 7: 1970s film look
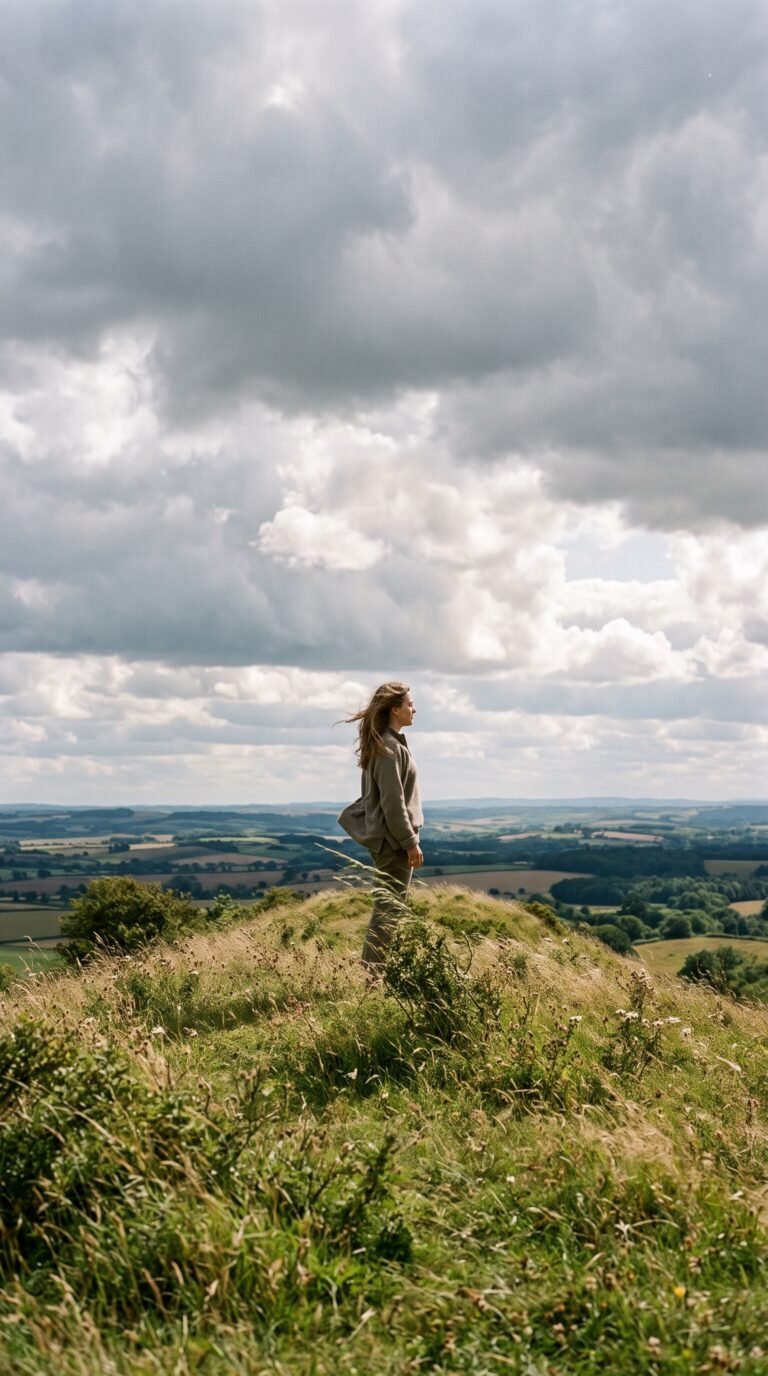


Scenario 8: Christmas sweater by the tree



Scenario 9: Black-and-white editorial portrait


Scenario 10: Watercolour painting
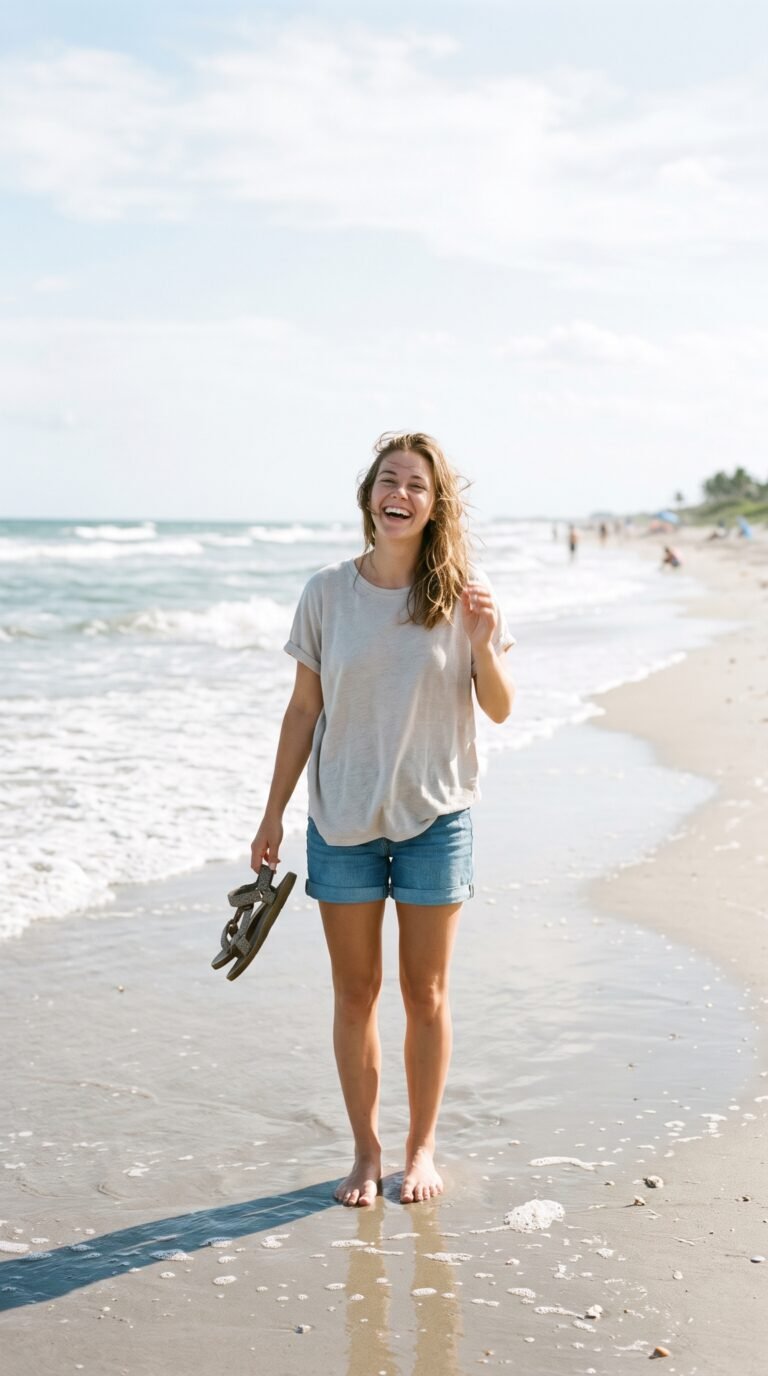
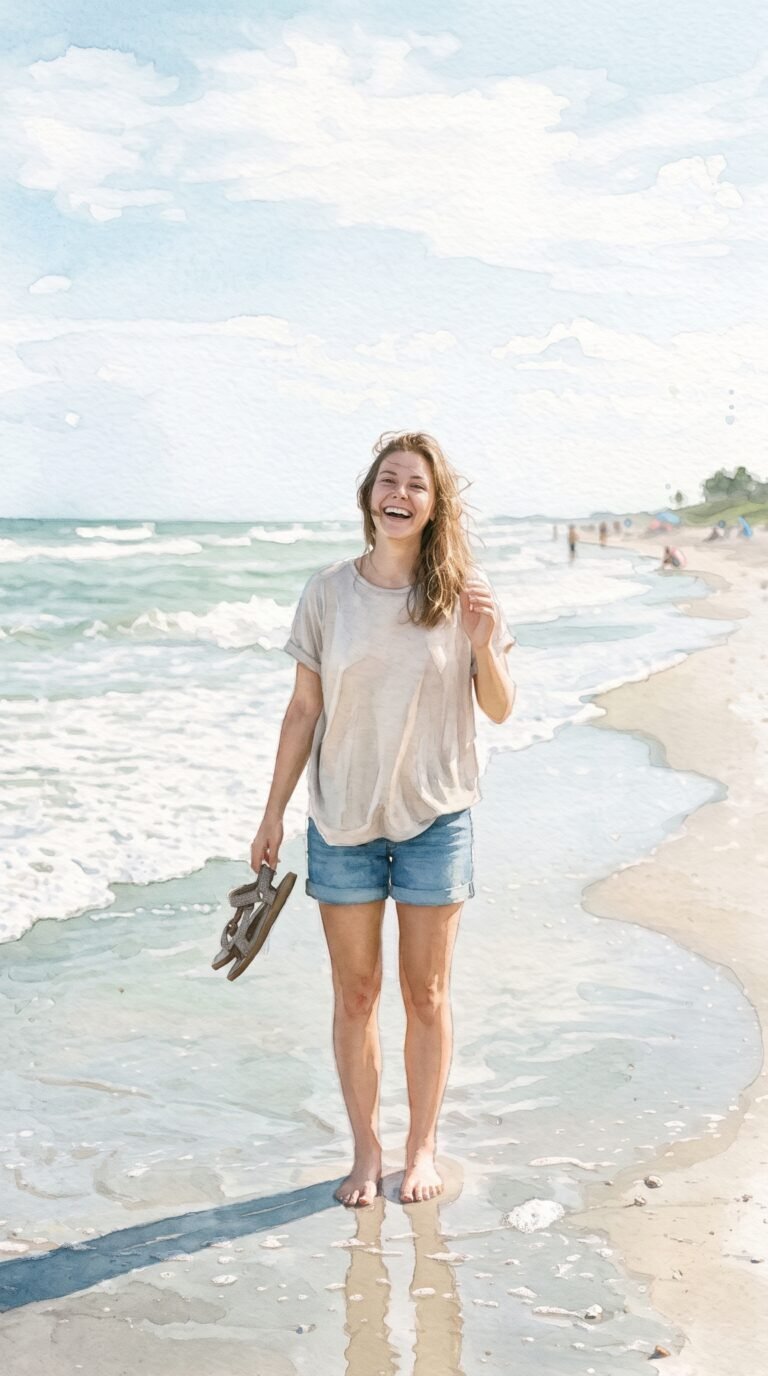
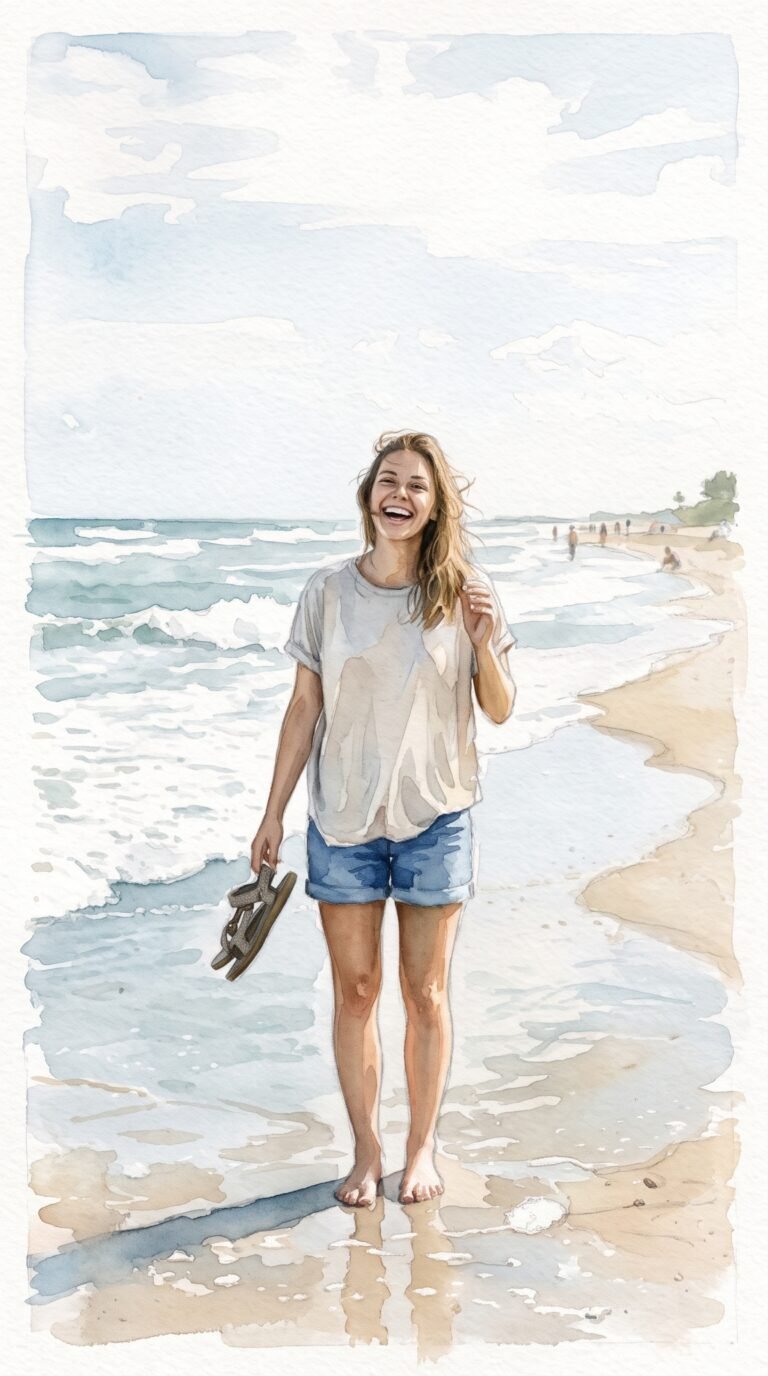

What we got wrong (full disclosure)
Three of our ten scenarios had wording mistakes, all ours, all from designing prompts from memory of the input photos instead of re-checking them:
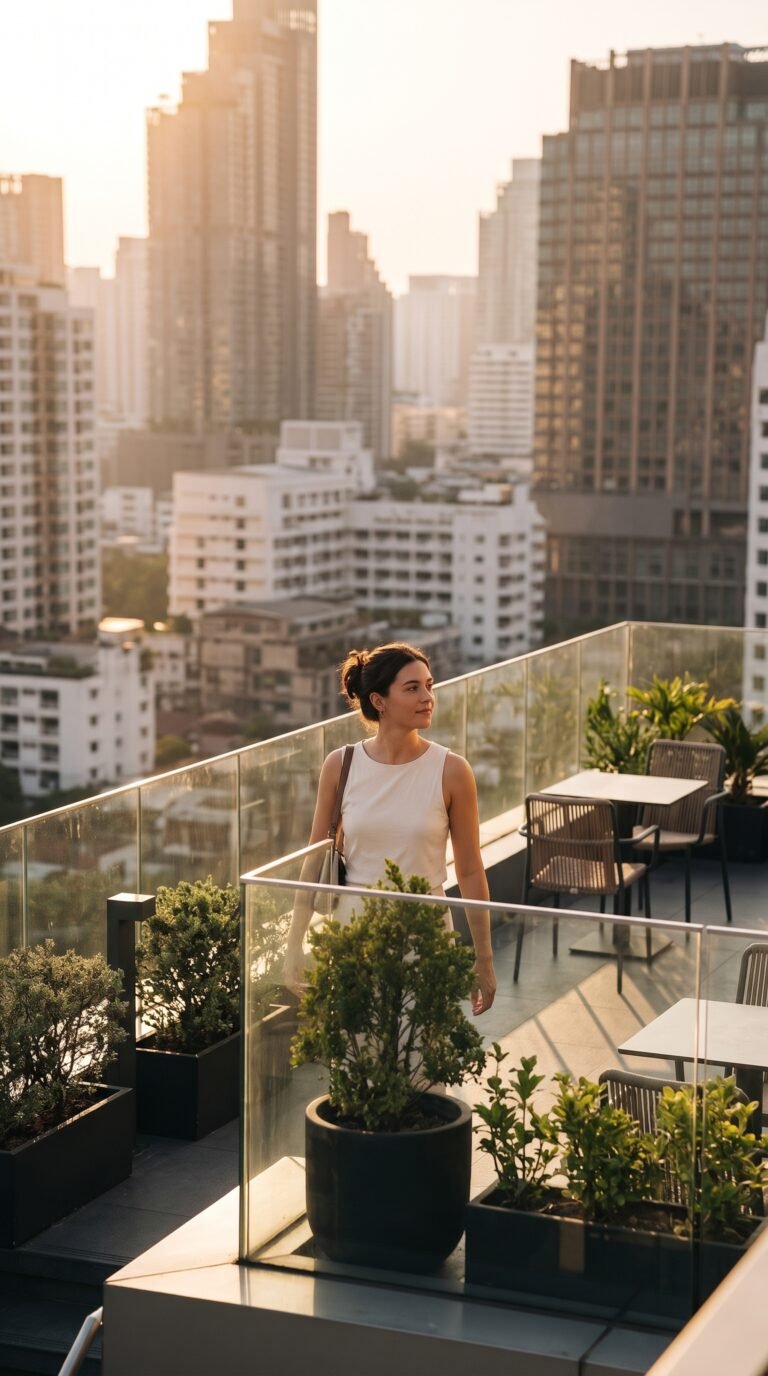
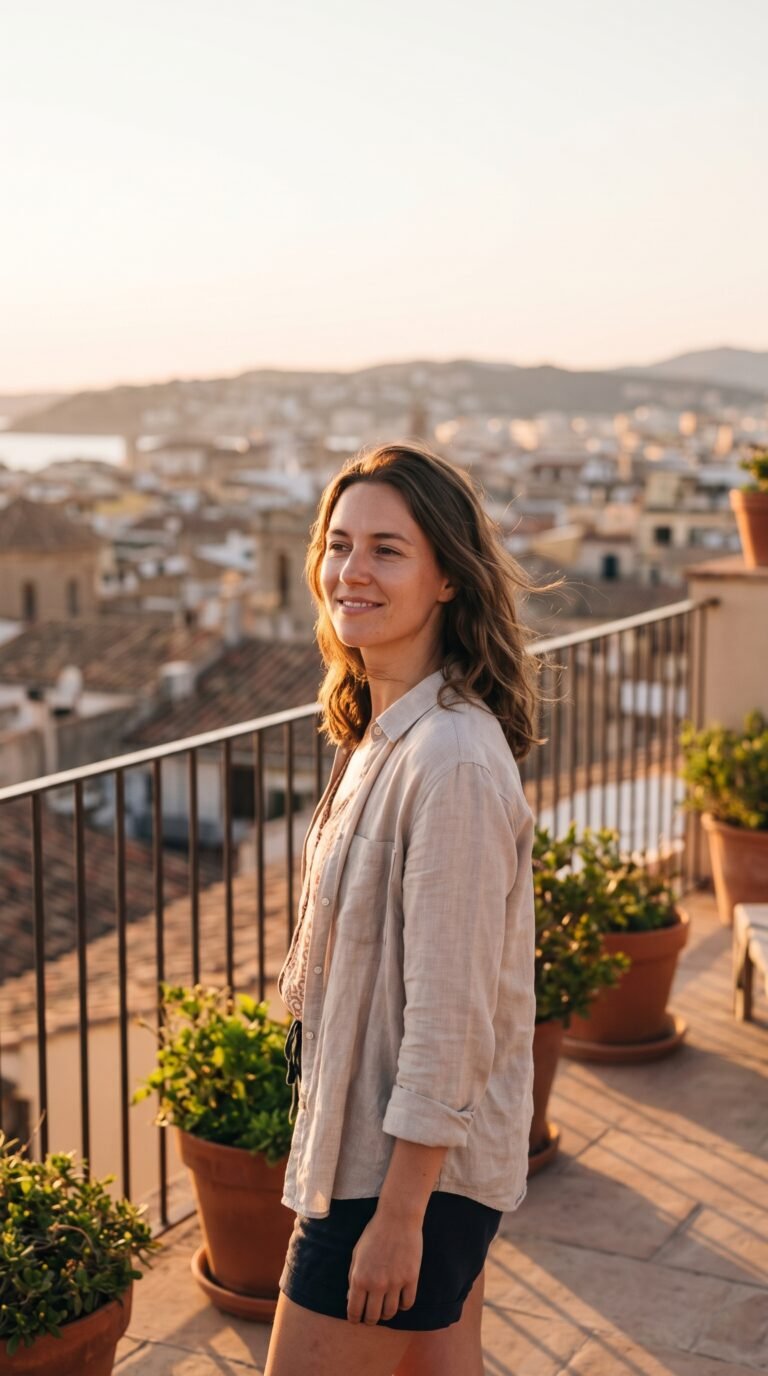
- Scenario 1 was excluded. Its prompts were written for “the woman in my photo”, but the input photo was a man in distant profile. Gemini invented a different woman at all three lengths. We excluded it from the averages and publish its images below — with one useful lesson attached: when a prompt’s premise contradicts the photo, no length saves it.
- Scenarios 6 and 8 contained a wrong-gender word (“the man in my photo” for photos of women). We kept them in the dataset because the faces were clearly judgeable — and the results were interesting: in 5 of 6 runs Gemini followed the photo over the wrong word and kept the real person. The one run that obeyed the word instead was the long prompt in scenario 6 — the identity swap above.
- Scenario 9’s medium and long prompts mention replacing a “garden” background; the photo was actually indoors. The requested edit was identical across lengths, so the comparison stands, but the wording slip is recorded in the dataset.
We publish these mistakes because a test that hides its flaws isn’t a test. The method was written down before any image was generated, and the dataset includes every run — including the failures.
Excluded scenario 1: Rooftop at golden hour


Quick answers
Do longer prompts work better in Gemini?
Not clearly. Across 27 blind-scored first-try photo edits, short prompts (~30 words) averaged 13.8 out of 15 against 13.0 for medium and long prompts. Without the one flawed long-prompt run, short and long tie at 13.6. Adding detail past a clear short instruction did not reliably improve the result.
What is the best prompt length for a Gemini photo edit?
About 30 words was a safe default here: name the change, the setting and the light in one or two sentences, and include one clear line telling Gemini to keep the person’s face the same. Go longer only when the scene itself is complex.
Does prompt length affect face consistency?
Barely. Face-keeping averaged 4.3/5 for short prompts, 4.0 for medium and 4.1 for long, and without S6 long prompts score 4.5. Every length included a face-preservation line. The single worst face score (1/5) came from a ~200-word prompt that also contained a wrong-gender word.
How was this test run?
Ten photo edits, each written at three lengths (30 prompts total), run once each in Gemini — first try only, no retries or cherry-picking. Results were scored blind, without the scorer knowing which length produced which image. One scenario was excluded from the averages for a design error, disclosed in full on this page; all 30 runs, prompts and scores are published in the dataset below.
The dataset
All 30 runs — including the excluded scenario — are in the table below, in the open. Download the full data with the exact prompt text for every run: dataset CSV · view it as a Google Sheet.
| Scenario | Length | Words | Instruction /5 | Face /5 | Quality /5 | Total /15 | Notes |
|---|---|---|---|---|---|---|---|
| S1 | short | 30 | — | — | — | — | Excluded — false premise in the prompt (see above) |
| S1 | medium | 62 | — | — | — | — | Excluded — false premise in the prompt (see above) |
| S1 | long | 183 | — | — | — | — | Excluded — false premise in the prompt (see above) |
| S2 | short | 30 | 5 | 5 | 5 | 15 | Full edit; face faithful; polished clean result |
| S2 | medium | 64 | 5 | 4 | 4 | 13 | Full edit; face close but hair restyled fuller on top; bg darker/textured |
| S2 | long | 185 | 5 | 5 | 5 | 15 | Full headshot edit; face and hair faithful; even light; clean grey bg |
| S3 | short | 30 | 5 | 3 | 4 | 12 | Full anime redraw; clean cel shading; face generic anime, moderate likeness |
| S3 | medium | 69 | 5 | 3 | 4 | 12 | Full anime redraw incl. background; outfit/pose kept; face generic anime |
| S3 | long | 197 | 4 | 3 | 4 | 11 | Anime conversion but background stays near-photo; face generic anime, moderate likeness |
| S4 | short | 31 | 5 | 4 | 5 | 14 | Neon street + clear umbrella delivered; face close in 3/4 view; strong reflections |
| S4 | medium | 72 | 5 | 4 | 4 | 13 | Neon + umbrella delivered; face close; slightly glossy finish |
| S4 | long | 216 | 5 | 5 | 5 | 15 | Neon + umbrella + mist delivered; face faithful to input |
| S5 | short | 33 | 5 | 5 | 5 | 15 | Beach sunset; hair up kept; face faithful; wet-sand reflection present |
| S5 | medium | 71 | 4 | 4 | 2 | 10 | Beach sunset delivered but lower body dissolves into mist artifact at sand line |
| S5 | long | 197 | 4 | 4 | 5 | 13 | Beach sunset clean; but hair worn down long vs input bun – hairstyle not kept |
| S6 | short | 32 | 5 | 5 | 5 | 15 | Same flawed premise; this run kept the real woman – suit, office, windows, bun, face all faithful |
| S6 | medium | 69 | 5 | 4 | 5 | 14 | Kept the real woman; suit + office delivered; face very close, slight softening |
| S6 | long | 196 | 3 | 1 | 4 | 8 | DESIGN FLAW scenario (prompt says 'man', input is a woman): this run replaced her with an invented man in a suit; image itself… |
| S7 | short | 31 | 4 | 5 | 4 | 13 | Warm faded grade applied mildly; scene and profile identical to input |
| S7 | medium | 69 | 5 | 5 | 4 | 14 | Furthest fade – pale sky, soft album-print feel; scene identical |
| S7 | long | 197 | 4 | 5 | 4 | 13 | Warm faded grade; subtle grain; scene identical |
| S8 | short | 32 | 5 | 4 | 4 | 13 | Kept the real person; sweater+tree+mug delivered; busier sweater pattern, slightly cluttered |
| S8 | medium | 69 | 5 | 4 | 5 | 14 | Gender-wording flaw (prompt says 'young man', input is a woman) but run kept the real person; sweater+tree+mug delivered |
| S8 | long | 210 | 5 | 5 | 5 | 15 | Kept the real person; reindeer sweater, tree with star, presents, armchair; face faithful |
| S9 | short | 29 | 5 | 4 | 5 | 14 | Most dramatic chiaroscuro; deep shadow side; top renders much darker than input's light knit |
| S9 | medium | 70 | 5 | 4 | 5 | 14 | Strong modelling light; rich tones; face close |
| S9 | long | 211 | 4 | 5 | 4 | 13 | B&W dark-bg portrait delivered; side light mild, more even than dramatic; face faithful |
| S10 | short | 29 | 5 | 4 | 4 | 13 | Softer paler watercolour; face recognisable; gentle handling |
| S10 | medium | 70 | 5 | 4 | 4 | 13 | Watercolour with paper-edge border effect; palest handling; face recognisable |
| S10 | long | 210 | 5 | 4 | 5 | 14 | Rich watercolour washes, pigment edges; same pose/laugh; face recognisable |
The images, charts and data on this page may be reused under CC BY 4.0 with credit to PromptTick and a link back to this test.
Copy-paste citation
HTML:<a href="https://prompttick.com/prompt-length-test-gemini/">Prompt Length Test: Do Longer Gemini Prompts Actually Work Better? (30 First-Try Edits)</a> — PromptTick (2026)
Markdown:[Prompt Length Test: Do Longer Gemini Prompts Actually Work Better? (30 First-Try Edits)](https://prompttick.com/prompt-length-test-gemini/) — PromptTick (2026)
Plain text:PromptTick. (2026). Prompt Length Test: Do Longer Gemini Prompts Actually Work Better? (30 First-Try Edits). https://prompttick.com/prompt-length-test-gemini/
What this changes at PromptTick: starting this month, every new detailed prompt we publish will also carry a short ~30-word version alongside it — so you can start simple and add detail only where your edit actually needs it. This test is why.